
Top AI Repos — open-source AI, indexed and scored
Top AI Repos tracks AI repositories on GitHub and answers two different questions about each one: is it moving right now, and would you bet a product on it.
Top AI Repos tracks AI repositories on GitHub and answers two different questions about each one: is it moving right now, and would you bet a product on it.

A powerful AI library that bridges Large Language Models (LLMs) with video processing frameworks like YOLO, enabling seamless integration of vision and language for advanced video understanding, object detection, and contextual analysis.
| Date | Stars |
|---|---|
| 2026-07-31 | 520 |
| 2026-08-06 | 496 |
| 2026-08-15 | 495 |
| 2026-08-18 | 494 |
| 2026-08-21 | 479 |
| 2026-08-24 | 478 |
| 2026-08-25 | 461 |
| 2026-08-26 | 457 |
| 2026-08-27 | 450 |
| 2026-08-30 | 445 |
| 2026-09-18 | 438 |
| 2026-09-19 | 431 |
| 2026-10-22 | 428 |
| 2026-10-24 | 425 |
| 2026-11-04 | 434 |
Today
+9 stars today
This week
+9 stars this week
This month
+3 stars this month
Momentum
80.0
growth rate 2.12%/day
# 🧠 Langvio: Natural Language Computer Vision <div align="center">  [](https://www.python.org/downloads/) [](https://opensource.org/licenses/MIT) [](https://badge.fury.io/py/langvio) [](https://langvio.readthedocs.io/) **Connect language models to vision models for natural language visual analysis** [🚀 Quick Start](#-quick-start) • [📖 Documentation](https://langvio.readthedocs.io/) • [🎯 Examples](#-examples) • [🔧 Installation](#-installation) • [🤝 Contributing](#-contributing) </div> --- ## ✨ What is Langvio? Langvio bridges the gap between **human language** and **computer vision**. Ask questions about images and videos in plain English, and get intelligent analysis powered by Qwen-VL — a vision-language model that parses queries, grounds objects, describes scenes, and generates explanations through separate model calls. The current source version is **0.0.11** (Python **3.10–3.12**). ### 🎯 Key Features - **🗣️ Natural Language Interface**: Ask questions like "Count all red cars" or "Find people wearing yellow" - **🎥 Multi-Modal Support**: Works with both images and videos - **🤖 Qwen-VL at the Core**: Qwen-VL powers both grounding (detection) and language (query parsing, explanations), with independently configurable vision and language processors - **☁️ API by Default, Local Fallback**: Runs over an OpenAI-compatible endpoint (OpenRouter by default) with an API key; falls back to in-process Qwen2.5-VL weights when `langvio[vlm]` is installed and no key is set - **📦 Legacy YOLO-World Path**: Classic open-vocabulary detection via YOLO-World v2 + ByteTracker still available for users who want it - **📹 Qwen Video Tracking**: Sparse keyframe grounding, label-aware track association, and CPU optical flow between keyframes; interpolation is the fallback - **🎯 Attribute Matching**: Descriptive queries such as "the person wearing glasses" select matching objects using detailed crops, including multiple views of video tracks - **📈 Video Summaries**: Estimated distinct objects, peak simultaneous counts, movement patterns, and centerline crossings - **📹 Legacy Tracking**: ByteTracker remains available with the YOLO-World path - **📊 Advanced Analytics**: Object counting, spatial relationships, temporal tracking - **🎨 Visual Output**: Generates annotated images/videos with detection highlights and tracking trails - **🌐 Web Interface**: Flask web app included for easy interaction - **🔧 Extensible**: Easy to add new models and capabilities ## 🖼️ Latest Example Outputs Annotated classroom outputs from the current Qwen-VL pipeline. ### Image: Chair Detection 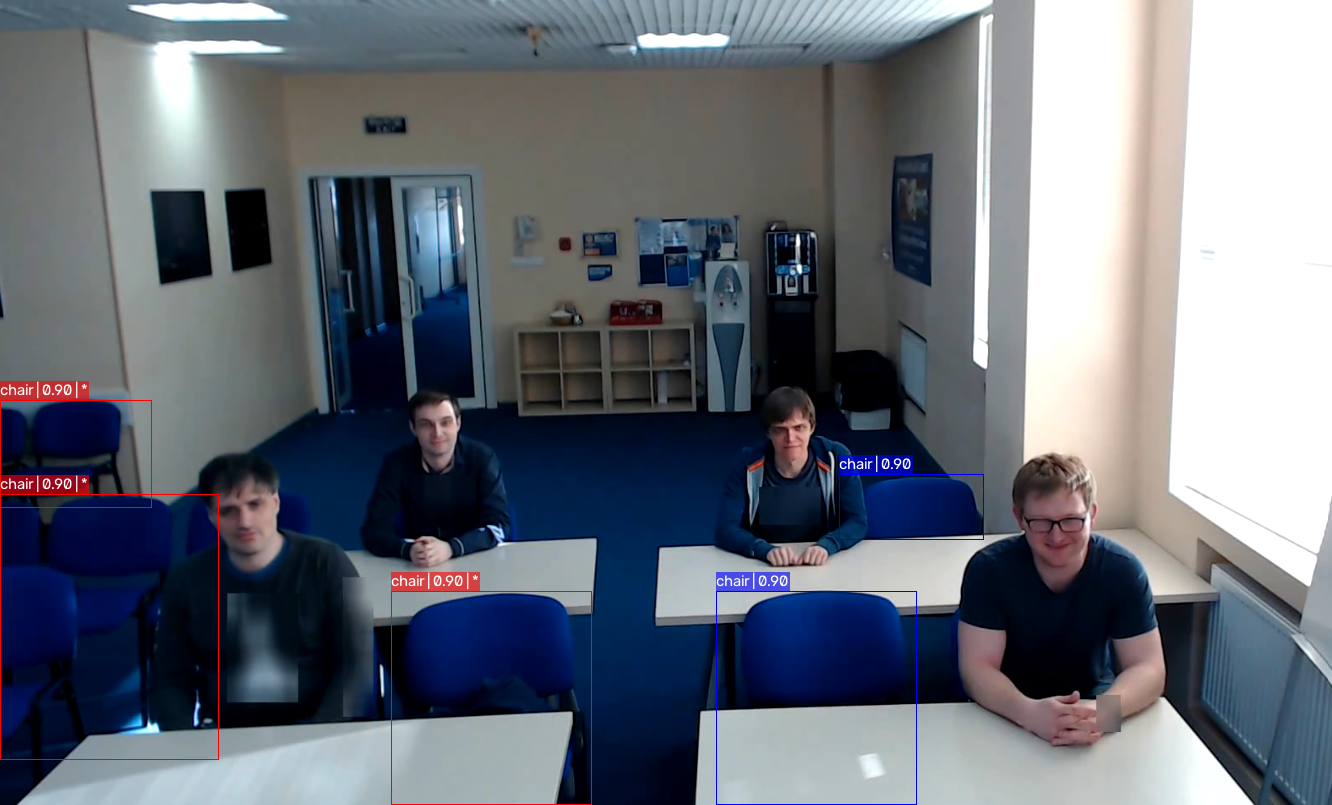 The supplied image shows detected chairs with bounding boxes and labels. Displayed confidence values are assigned by the Qwen processor, rather than calibrated model probabilities. ### Video: Classroom Analysis [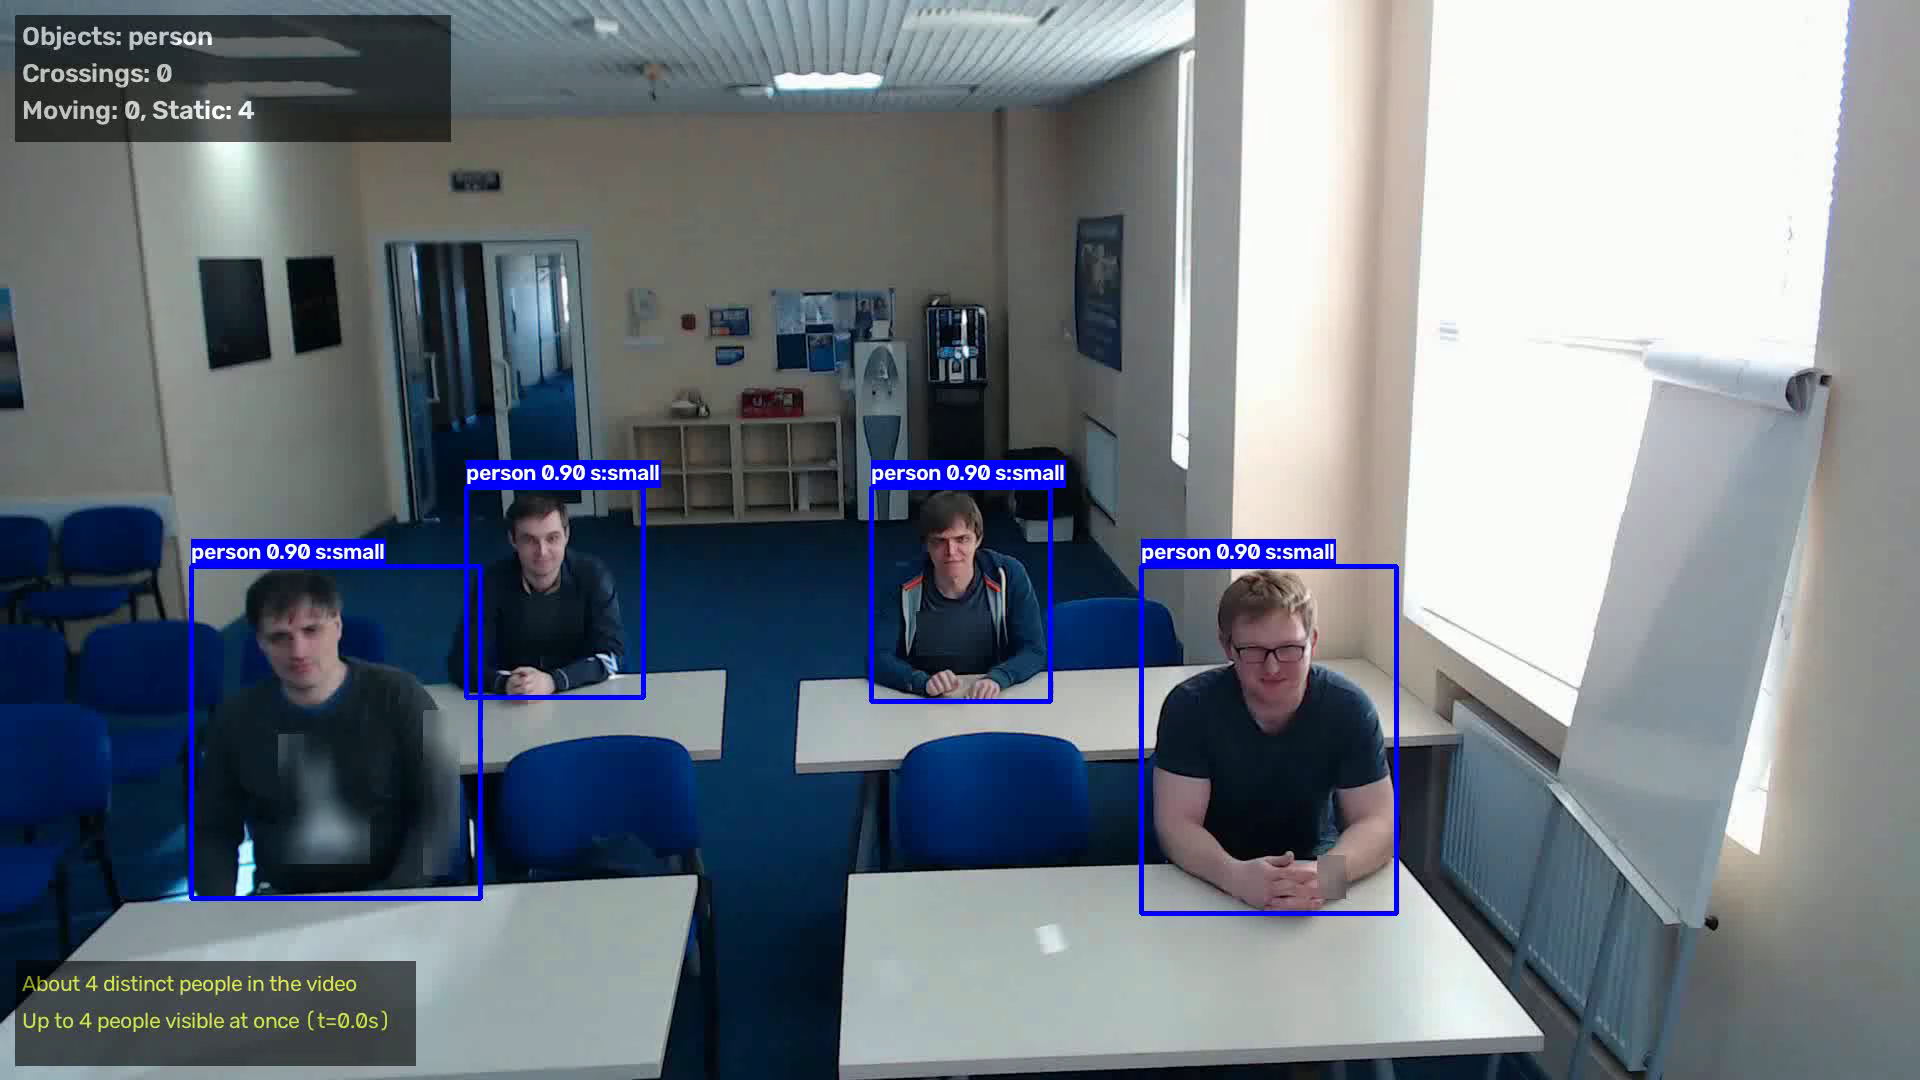](https://github.com/MugheesMehdi07/langvio/raw/refs/heads/master/assets/classroom_processed.mp4) [Watch or download the processed video](https://github.com/MugheesMehdi07/langvio/raw/refs/heads/master/assets/classroom_processed.mp4) (32.8 seconds, 1920 × 1080, 30 fps). Click the video preview or the link to open the MP4. The README uses a clickable preview that links directly to the video file. The file uses H.264 with `yuv420p` and fast-start metadata for browser playback. ## 🔧 Inst
Excerpt of 25,028 characters
Read on GitHub
84

23

@actions
3

3
Would you bet a product on this? Bounded 0–100 and slow moving.
matched fp:95cf627677410ff3, desc:object detection