

These are the collections of scripts that scrape's social media profiles


CoreClaw — Web Scraping Platform & Ready-to-Use Data Extraction Tools
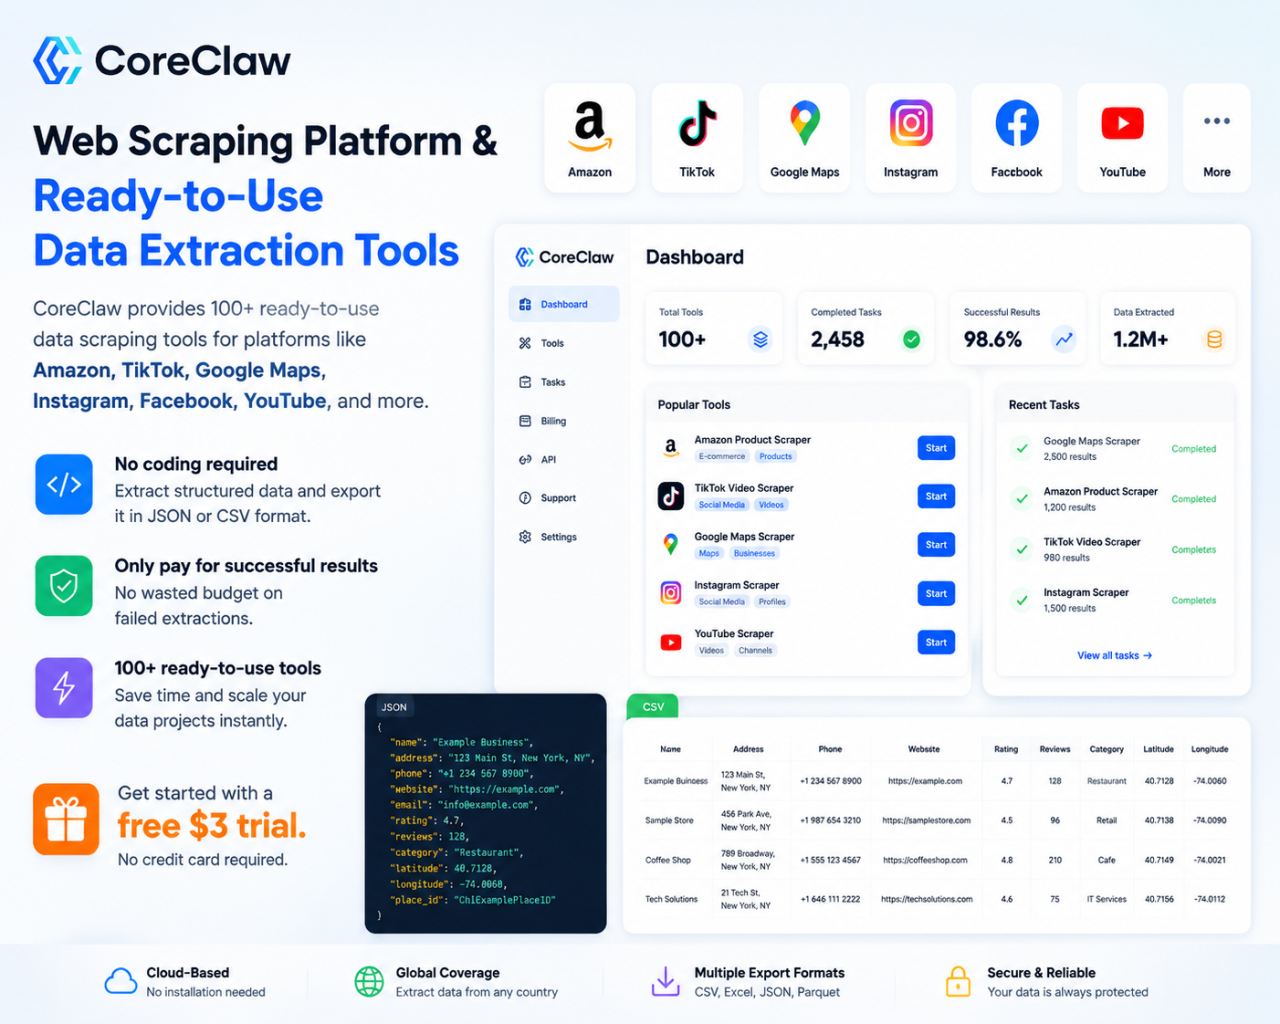
CoreClaw provides 100+ ready-to-use data scraping tools for platforms like Amazon, TikTok, Google Maps, Instagram, Facebook, YouTube, and more.
- 🚫 No Coding Required — Extract structured data effortlessly.
- 🔄 Flexible Formats — Export seamlessly to JSON or CSV format.
- 🛡️ Pay-Per-Success — Only pay for successful results with no wasted budget on failed extractions.
- TikTok
- Medium
- Quora
- Github
- Install dependencies mentioned inside requirement.txt by opening terminal in project's directory and enter command
pip install -r requirement.txt
- Open terminal in project's directory and enter command
example
python SCRIPT_NAME USERNAME --browser BROWSER_NAMEifpython twitter.py barackObama --browser firefox--browserargument is not passed, chrome is used by default. currently only firefox and chrome is supported- for more help enter command
examplepython SCRIPT_NAME -hNote: Pinterest, Medium and Twitter script doesn't need browser. Just use it likepython instagram.py -hpython pinterest.py usernameGithub reads the GitHub REST API directly (python github.py username); a browser is only started as a fallback for the yearly-contribution count (skip it with--no-contributions).
All scraper scripts share one fetching mechanism: scraper_engine.py. Each script first tries a fast curl_cffi request (browser-impersonated TLS, no browser started) and automatically falls back to a real browser through SeleniumBase UC mode (undetected-chromedriver) when the HTTP attempt does not return usable data. Extra optional flags are available, e.g.:
python facebook.py USERNAME --engine auto     # curl_cffi first, then UC browser (default)
python facebook.py USERNAME --headed          # run the fallback browser non-headless
python facebook.py USERNAME --json            # print the result as JSON
The engine is extensible: new backends (a paid API service, FlareSolverr, ...) can be plugged in without touching the scripts - see the module docstring of scraper_engine.py.

If You have suggestions for more social media. Let me know 😉

