





Prometheus exporter for NVIDIA GPUs, reading metrics directly from the NVIDIA driver library (NVML) or through nvidia-smi.
Runs on Linux, Windows and macOS, on bare metal, in Docker or on Kubernetes.
Warning
Heads up: this is a side project I maintain in my spare time. I might take a long time to look at issues or PRs, or not get to them at all. Sorry in advance, and thanks for understanding.
The exporter collects utilization, memory, power, thermals, clocks, throttling reasons, ECC errors, encoder/decoder stats and per-process GPU usage, and exposes them as nvidia_smi_* Prometheus metrics.
It supports two collection backends that emit identical metric names, labels and values for every shared field (see CONFIGURE.md):
- Native NVML (
nvml, recommended): readslibnvidia-ml.so.1on Linux andnvml.dllon Windows in-process without spawningnvidia-smi. In addition to the shared metrics, it exports families only the driver library provides: XID error counters, total energy consumed, per-MIG-instance metrics, whole-GPU GPM activity ratios, PCIe throughput and replay counters, NVLink byte counters, graphics processes and per-process engine utilization. On Linux it ships in the-nvmlcontainer images (:X.Y.Z-nvml) andnvidia_gpu_exporter-nvml_*archives withnvmlenabled by default. On Windows it is included innvidia_gpu_exporter.exeand enabled with--collect.backend=nvml. nvidia-smisubprocess (exec): runsnvidia-smiand parses its CSV output. It remains the compiled default in the plain (non--nvml) images, archives,deb/rpmpackages, and Windows binary for 1.x compatibility, works as a static binary with zero C bindings on any platform wherenvidia-smiexists, isolates the exporter from stuck driver calls, auto-discovers brand-new driver fields, and supports custom wrapper commands (ssh,sudo).
On a Linux machine with the NVIDIA driver and the NVIDIA Container Toolkit (using the -nvml image flavor):
docker run -d --name nvidia_gpu_exporter --restart unless-stopped \
  --gpus all -e NVIDIA_DRIVER_CAPABILITIES=utility -p 9835:9835 \
  utkuozdemir/nvidia_gpu_exporter:latest-nvml
curl http://localhost:9835/metrics
Use utkuozdemir/nvidia_gpu_exporter:latest instead if you prefer the static nvidia-smi subprocess backend.
No GPU at hand? nvidia_gpu_exporter --collect.backend demo serves realistic synthetic metrics on any machine. For Windows, macOS, packages, Kubernetes and running without Docker, see INSTALL.md.
- Consumer and prosumer GPUs (GeForce/RTX), workstations and gaming rigs, where datacenter fleet tooling exposes little or does not run
- Small Kubernetes clusters, edge boxes and homelabs that want GPU metrics, alerts and dashboards without installing the NVIDIA GPU Operator stack
- Virtualized or restricted setups (vGPU guests, MIG slices, locked-down containers, WSL2)
- Mixed fleets of old and new cards across Linux and Windows that need one exporter with a uniform metric schema
- Remote monitoring of another host over an
sshwrapper command (execbackend)
If you run a large datacenter fleet on Kubernetes with the GPU Operator already installed, DCGM-exporter is probably the better fit.
Demo mode serves realistic synthetic metrics covering the full NVML surface, with no GPU, driver or Linux required:
nvidia_gpu_exporter --collect.backend demoBy default it simulates two H200 GPUs with fluctuating values, a MIG topology and an XID error history. The simulated setup is configurable, see CONFIGURE.md.
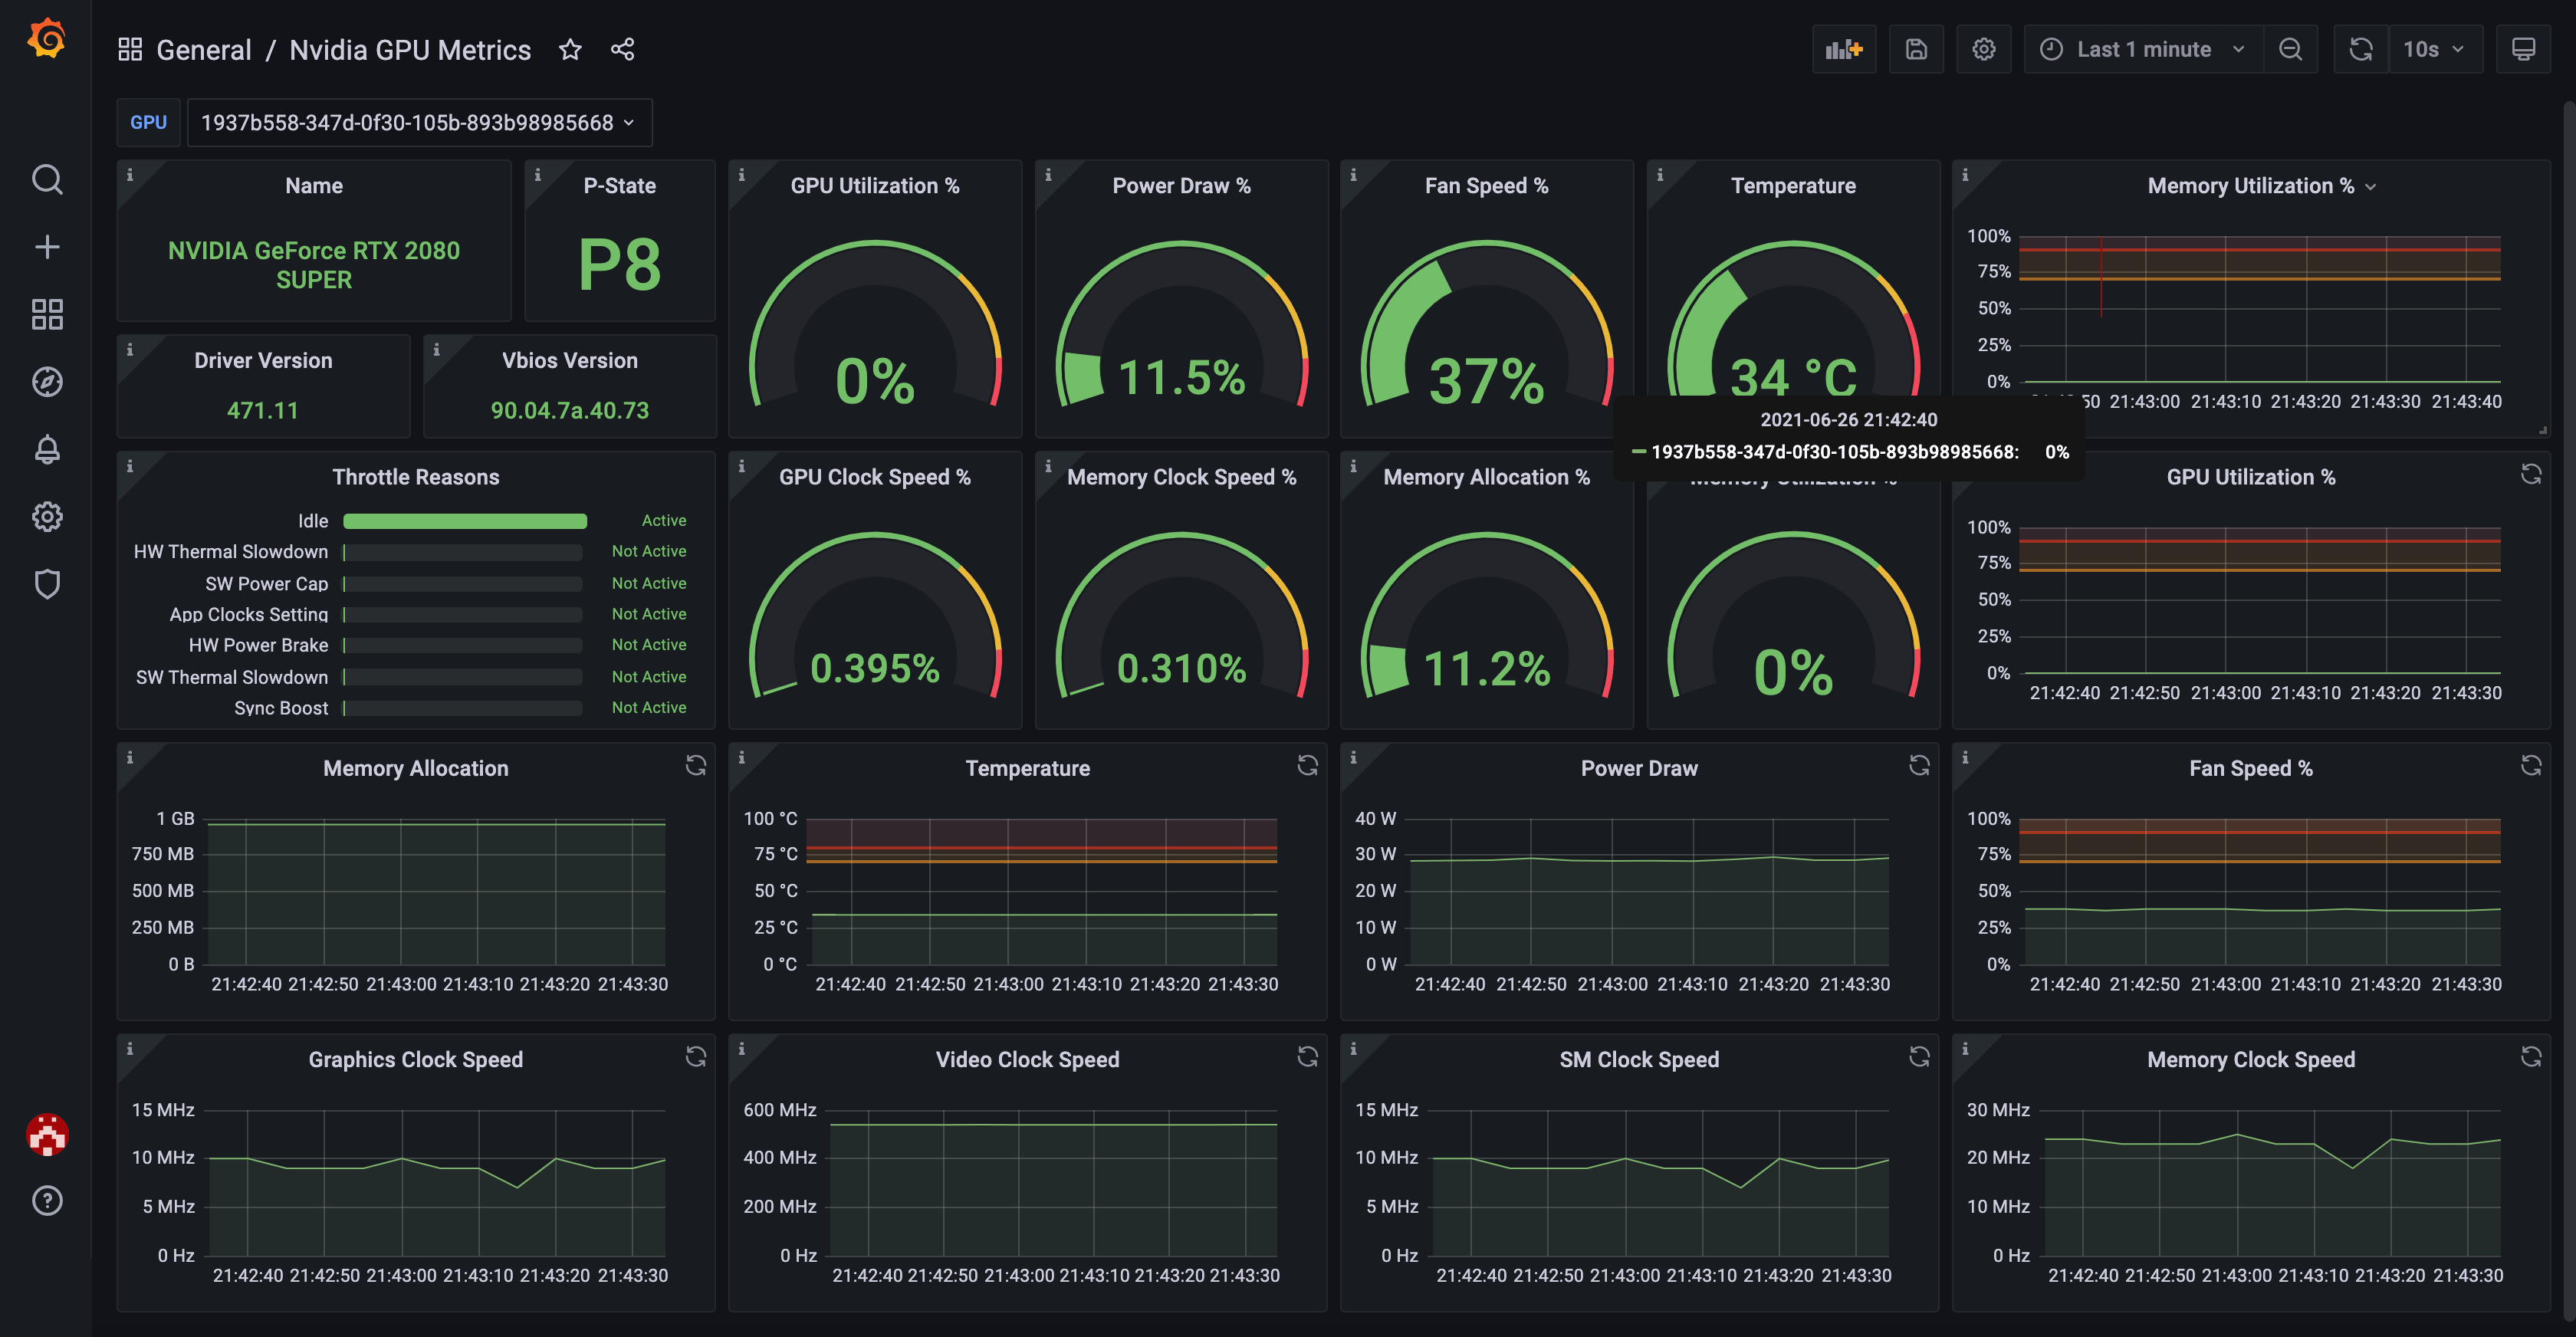
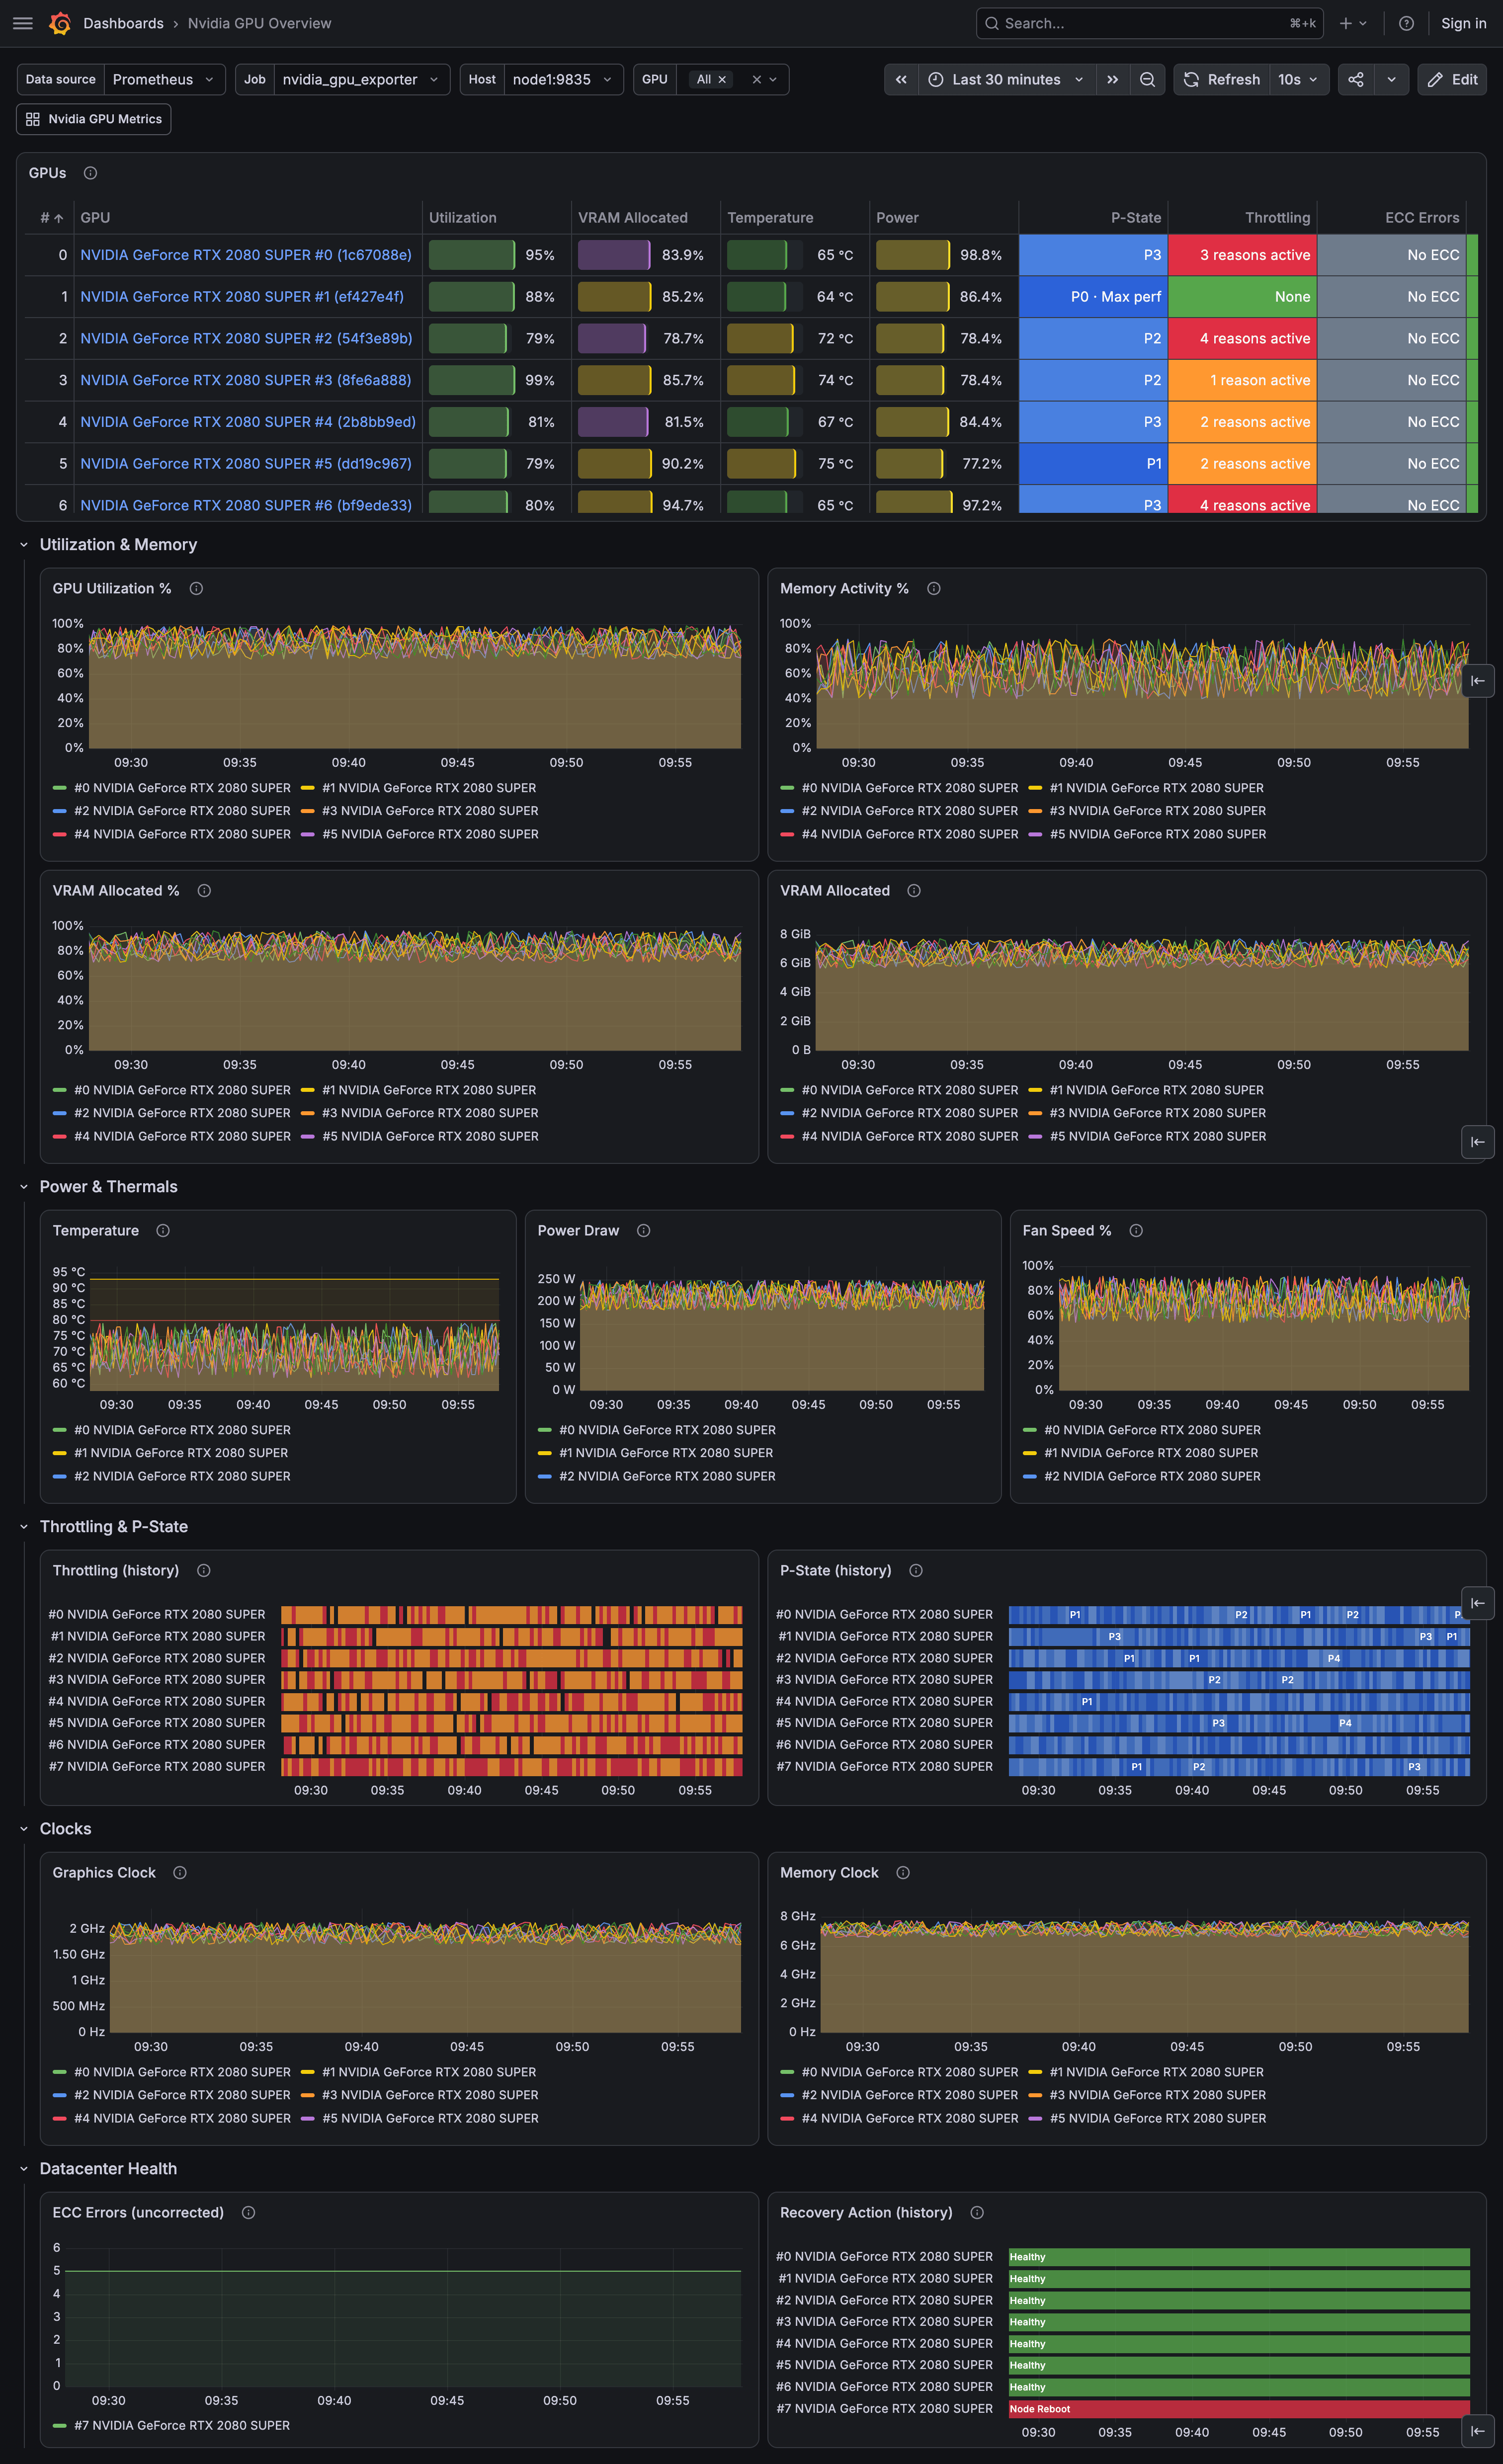
There are two official Grafana dashboards, and they link to each other in Grafana:
- Nvidia GPU Metrics (ID
14574), the per-GPU detail view. - Nvidia GPU Overview (ID
25547), which compares all GPUs of a node side by side and drills down into the detail dashboard.
Import either by ID in Grafana (Dashboards - New - Import), or enable grafanaDashboard in the Helm chart to get both provisioned automatically. The JSON files also live under docs/grafana.
INSTALL.md covers every platform:
- Linux:
deb/rpmpackages, static or-nvmlbinaries, and a systemd unit - Docker:
:X.Y.Z-nvmland:X.Y.Zcontainer images on Docker Hub and GHCR - Kubernetes: the Helm chart on Artifact Hub (including Prometheus alert rules and Grafana dashboards) or a plain DaemonSet
- Windows:
winget, Scoop, a native Windows service, or an all-in-one PowerShell script that also sets up Prometheus and Grafana - macOS: binary archive for remote scraping over SSH
Release artifacts, container images, and Helm charts are signed and carry GitHub build provenance attestations. See INSTALL.md for verification commands and SECURITY_MODEL.md for the security model.
- CONFIGURE.md: flags, collection backends, per-process metrics, background collection, timeouts and
/-/gpu-healthy. - METRICS.md: metric families, labels, enum mappings, MIG and XID semantics, and Kubernetes /
vLLMPromQL joins.
See CONTRIBUTING.md for the development setup, ROADMAP.md for what is planned, and GOVERNANCE.md for how decisions are made.
The test suite replays recorded nvidia-smi output and NVML symbol lists from real hardware across GPU models, driver versions and operating systems. Recording a capture from a GPU or driver version not yet in the corpus takes one command:
./internal/captures/collect.sh # add --load for an under-load sample tooIt runs read-only, masks identifiers (GPU UUID, serial, hostname) by default, and writes one .txt file. Commit it and open a PR, or attach it to an issue. See internal/captures/README.md.


